Quick answer: Suno AI works by using large AI models trained on music to learn patterns — melody, rhythm, harmony, instruments, vocals and song structure. When you type a style and lyrics, the model predicts audio step by step that fits your description, a bit like how chatbots predict text. It generates vocals and instruments together as one piece of audio, which is why results sound like full songs. Because generation involves randomness, the same prompt gives different results each time.
You don’t need to understand AI to use Suno, but knowing the basics helps you write better prompts and get more consistent results. Suno hasn’t published every technical detail, so this is a simplified, general explanation.
The process in five steps
| Step | What happens |
|---|---|
| 1. Training | The model learns patterns from large amounts of music and related text |
| 2. Your prompt | You give a style, lyrics and settings |
| 3. Understanding | The model turns your words into an internal representation |
| 4. Generation | It predicts audio piece by piece, guided by your prompt |
| 5. Output | Audio is decoded into a song you can play |
Step 1: Training — learning what music sounds like
Like other generative AI, Suno’s models are trained on large datasets so they can learn patterns: how a chorus usually lifts, how a trap beat is built, how a soul singer phrases a line, which instruments appear in which genres. The model doesn’t store songs like a library; it learns statistical patterns that let it make new audio. How Suno trained its early models became the centre of major lawsuits, and since 2026 Suno has moved to licensed models built with partners such as Warner Music Group. See the Suno lawsuit timeline.
Step 2: Turning sound into “tokens”
Raw audio contains tens of thousands of numbers per second, which is too much for an AI to predict directly. Music models like Suno’s are generally believed to compress audio into smaller units — often called audio tokens — that capture the important information. The model learns to predict these tokens, and a decoder turns them back into sound. This is similar to how text AI predicts words or word pieces. It’s one reason Suno can generate minutes of music in seconds.
Step 3: Understanding your prompt
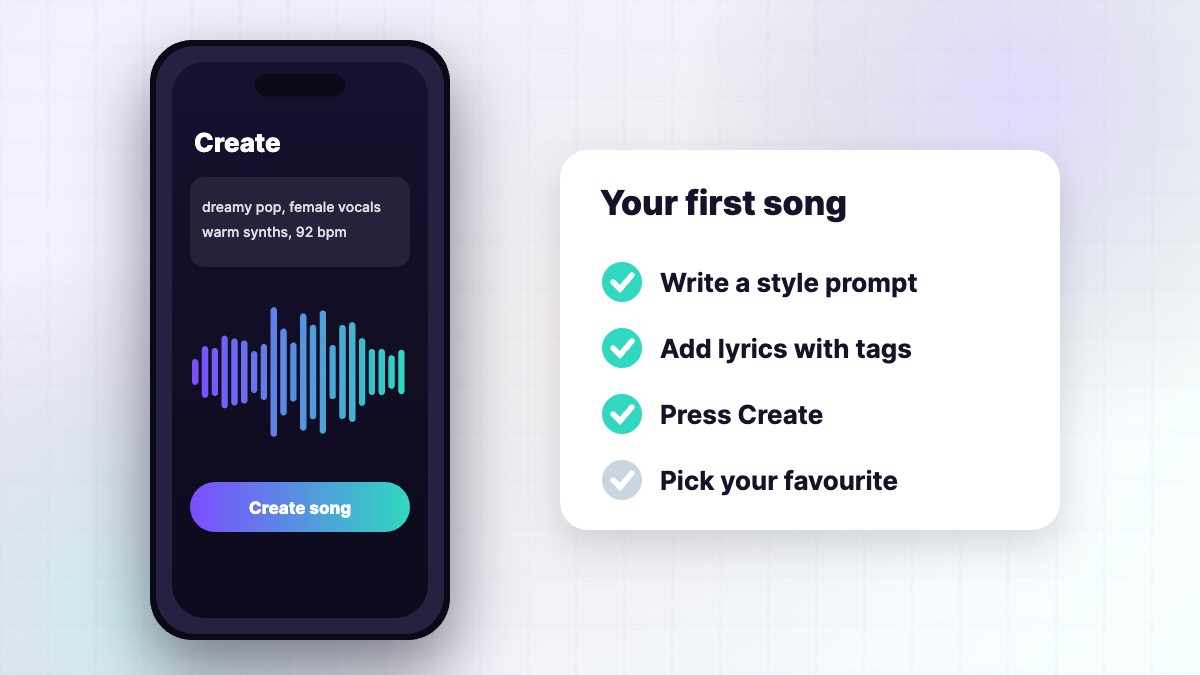
Your style text, lyrics and settings are turned into signals that guide generation. Early words in the style often carry more weight, which is why putting the genre first helps. Lyrics guide what is sung and where sections start, especially when you use tags like [Verse] and [Chorus]. Sliders like Weirdness and Style Influence change how closely the model follows your text and how adventurous it is. Learn more in our style prompts guide.
Step 4: Generation — predicting the song
The model generates the song step by step, each new piece depending on what came before and on your prompt. That’s how it keeps a consistent key, tempo and voice, and builds verses into choruses. A degree of randomness is added so results are creative rather than identical. That’s why you get two different songs for each generation and why trying again can give a better result.
How vocals and lyrics work
Suno generates singing and music together, so the voice sits naturally in the mix. The lyrics tell the model what words to sing; the style tells it what kind of voice and delivery to use. Mispronunciations happen when words are rare, ambiguous or written in a way the model doesn’t expect — which is why phonetic spelling helps. Personas and verified Voices guide the model towards a specific vocal identity. See Suno Voices and Personas.
Different models, different behaviour
| Model | Behaviour |
|---|---|
| v6 | Polished and reliable; follows prompts closely |
| v6-wild | More random and experimental |
| v6-mini | Faster and lighter; available to everyone |
Newer models are trained and tuned to give better audio, follow prompts more closely and support features like section editing and mashups. See Suno v6 explained.
How editing features work
Features like extend, cover and v6 section editing reuse parts of an existing song as context. Extend continues from a chosen point; cover keeps melody and lyrics while changing style; section editing regenerates one part while keeping the rest. All of them use the same idea: give the model more context so the result fits.
What this means for your prompts
- Lead with the genre — early words matter.
- Be specific but short — clear signals beat long paragraphs.
- Tag your lyrics — structure helps the model plan the song.
- Expect variation — generate a few times and pick the best.
- Use editing — give the model context instead of starting over.
- Avoid contradictions — conflicting words confuse the model.
Practical examples are in our Suno prompts guide and meta tags cheat sheet.
Why Suno sometimes gets things wrong
- Unusual words: the model guesses pronunciation.
- Overloaded prompts: too many instructions compete.
- Long lyrics: the model may rush or skip lines.
- Rare genre mixes: fewer patterns to learn from.
- Randomness: sometimes it’s just an unlucky generation.
Safety systems
Suno adds filters to block artist names, copyrighted lyrics, uploads of copyrighted audio and harmful content. Voices require verification to prevent cloning. These systems sometimes flag innocent prompts; rephrasing usually helps. See Suno not working.
A simple analogy
Imagine a session band that has listened to an enormous amount of music. You hand them a lyric sheet and say “90s R&B slow jam, female singer, Rhodes”. They don’t copy a specific song; they play something new in that style, a little differently each time. Your lyric sheet and directions are your prompt. The better your directions, the closer they get to what’s in your head.
Will AI music keep improving?
Yes. Each new Suno model has improved audio quality, vocals and control. Future changes are likely to bring more precise editing, better pronunciation, longer songs and closer integration with production tools — alongside more licensing agreements with rights holders.
Do you need to understand all this?
Not at all. Millions of people use Suno without thinking about tokens or models. But knowing that the AI predicts music from your words explains why clear prompts, good structure and a few retries work so well. Start creating with our beginner’s guide, and come back to this page whenever you wonder why Suno did something unexpected.
Key terms explained
- Model: the AI system that makes the music.
- Training: how the model learned from data.
- Prompt: your style, lyrics and settings.
- Token: a small compressed unit of audio the model predicts.
- Generation: creating a new song from your prompt.
- Randomness: variation that makes each result different.
FAQ
Does Suno copy existing songs?
It’s designed to create new audio, and it blocks artist names and copyrighted lyrics. Training methods were the subject of lawsuits.
Why does the same prompt sound different each time?
Generation includes randomness, so each run explores different possibilities.
Does Suno use real singers?
The vocals are generated by the model, except when you use your own verified Voice.
What was Suno trained on?
Suno hasn’t published full details. Since 2026 it has moved to models built with licensed partners.
SunoMusicAI Guide is an independent website and is not affiliated with, endorsed by or sponsored by Suno, Inc. Features, prices and policies change often, so always check Suno’s official website for the latest details.

Leave a Reply